State Architecture
Real-Time Application State Management in Single-Page Apps
Exploring predictable state synchronization patterns across multi-user web environments.
Read Full ArticleArchitecting Hardware-Accelerated Graphical Interfaces for Modern Browsers
Modern browser environments demand ultra-fast graphical rendering routines to support vector dynamic artwork, complex layout generation, interactive gaming environments, and real-time canvas editors. When handling tens of thousands of interactive vector paths, custom typographic nodes, and high-resolution raster layers, standard DOM manipulation rapidly becomes a fatal performance bottleneck. Traditional web development practices that rely on updating HTML elements, modifying CSS properties, and handling native DOM events simply cannot scale to meet the raw throughput demands of modern graphical applications.
By bypassing continuous HTML DOM layout recalculations and targeting hardware-accelerated 2D and WebGL rendering pipelines directly, software engineers can maintain fluid 60 FPS (and even high-refresh-rate 120 FPS) performance metrics even under intense graphical loads. Transitioning from document-based rendering to low-level canvas pipelines requires a fundamental paradigm shift in how applications manage state, process draw calls, and schedule thread resources inside client environments.
Traditional web applications rely heavily on DOM element nodes tree structures. Every time an application alters a node's geometry, style, or position, browser engines must execute a series of expensive rendering pipeline steps across the main JavaScript thread: Recalculate Style, Layout (Reflow), Paint, and Composite. When building complex visual platforms, real-time user feedback requires low frame latencies—ideally under 16.67 milliseconds per frame. Executing layout algorithms for thousands of individual DOM elements quickly saturates CPU capacity, leading to dropped frames, input lag, and severe thermal throttling on mobile devices.
Transferring rendering operations to an HTML5 HTMLCanvasElement backed by GPU acceleration eliminates layout thrashing by maintaining state representations inside binary typed arrays and offscreen canvas buffers. Instead of instructing the browser engine to compute layout rules for structured HTML trees, developers write declarative or imperative commands that write color data directly into framebuffers managed by dedicated graphics hardware.
Key rendering optimizations focus on minimizing memory transfers between the CPU main thread and GPU framebuffers while maximizing parallel operations:
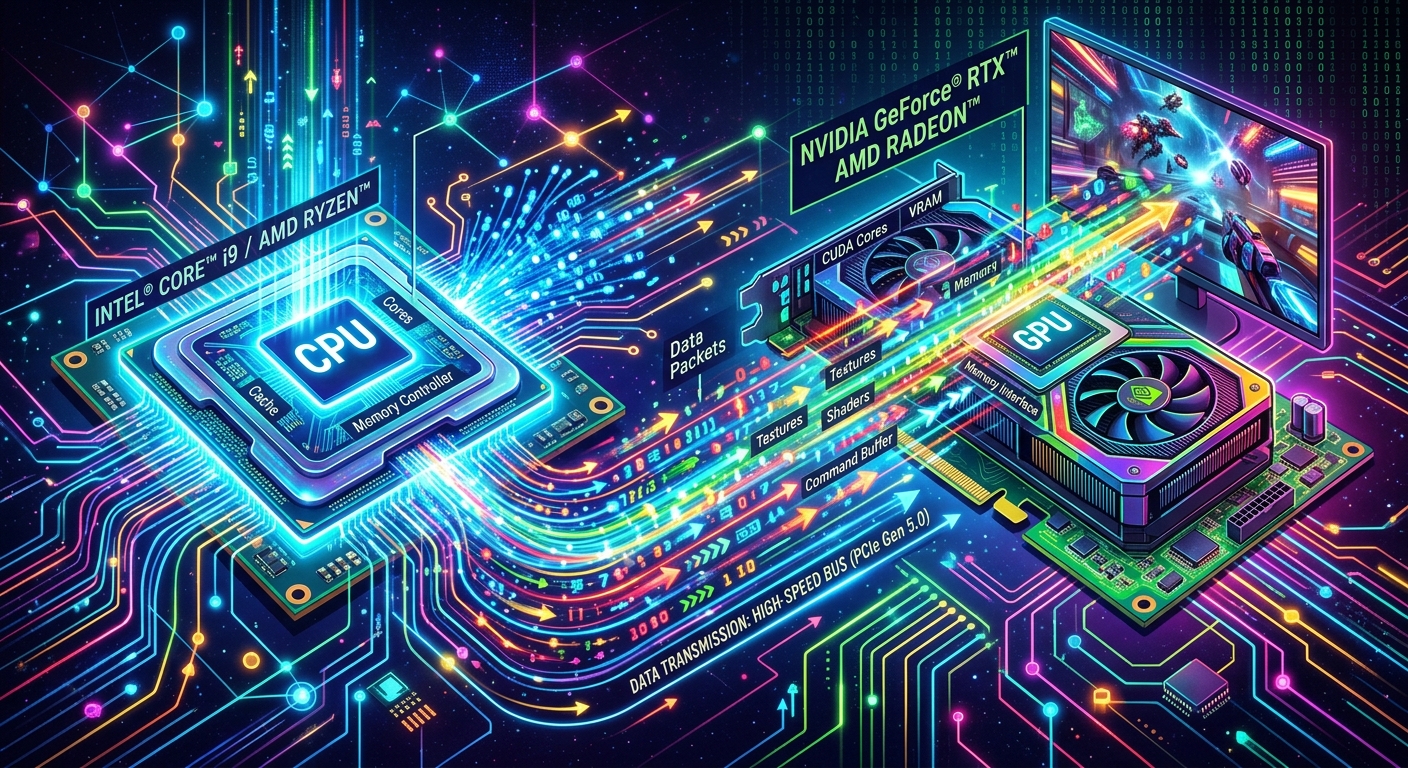
To choose the correct pipeline architecture for your software application, it is vital to understand the operational tradeoffs between traditional DOM node tree rendering, 2D Canvas Contexts, and direct WebGL/WebGPU hardware acceleration.
| Rendering Metric | DOM / SVG Rendering | 2D Canvas (Context 2D) | WebGL / WebGPU Pipeline |
|---|---|---|---|
| Max Object Capacity | ~1,000 to 2,000 Nodes | ~10,000 to 50,000 Objects | 100,000+ Instanced Sprites |
| Primary Bottleneck | Main-Thread Layout (Reflow) | CPU-to-GPU Canvas Draw Calls | GPU Shader Unit Execution |
| Memory Footprint | High (C++ DOM Nodes) | Moderate (Raster Buffers) | Low (Direct VRAM Buffer Arrays) |
| Development Complexity | Low (Standard CSS/HTML) | Medium (Imperative Canvas API) | High (Shaders, Matrices, Buffers) |
| Offscreen Worker Support | Not Supported | Supported via OffscreenCanvas | Supported via OffscreenCanvas |
Below is a production-grade JavaScript implementation illustrating an offscreen rendering strategy designed to cache static graphic objects into offscreen memory layers and blit them onto a primary visible canvas interface with sub-millisecond performance:
/**
 * Advanced High-Performance 2D Offscreen Canvas Pipeline Architecture
 * Designed for real-time graphics rendering with zero main-thread layout thrashing.
 */
class OffscreenGraphicPipeline {
    constructor(mainCanvasId, width, height) {
        this.mainCanvas = document.getElementById(mainCanvasId);

        // Request a desynchronized, low-latency 2D context to bypass compositor delay where supported
        this.ctx = this.mainCanvas.getContext('2d', {
            alpha: false,
            desynchronized: true,
            willReadFrequently: false
        });

        this.width = width;
        this.height = height;
        this.configureCanvasDimensions(width, height);

        // Initialize Offscreen Canvas Layer for Static Pre-Rendering Cache
        this.staticCanvasCache = document.createElement('canvas');
        this.staticCanvasCache.width = width;
        this.staticCanvasCache.height = height;
        this.staticCtx = this.staticCanvasCache.getContext('2d', { alpha: true });

        // Object Pool Array for Dynamic Nodes to avoid Garbage Collection
        this.dynamicNodePool = [];
        this.isDirty = true;

        // Bind Frame Animation Callback
        this.render = this.render.bind(this);
        this.animationFrameId = null;
    }

    configureCanvasDimensions(width, height) {
        // Correct for Device Pixel Ratio (DPR) to ensure crisp rendering on Retina screens
        const dpr = window.devicePixelRatio || 1;
        this.mainCanvas.width = width * dpr;
        this.mainCanvas.height = height * dpr;
        this.mainCanvas.style.width = `${width}px`;
        this.mainCanvas.style.height = `${height}px`;

        // Scale context coordinates to match design layout units
        this.ctx.scale(dpr, dpr);
    }

    /**
     * Pre-renders complex static paths to an offscreen buffer once.
     * Eliminates redundant CPU-bound arc/vector calculations every frame.
     */
    cacheStaticElements(graphicNodes) {
        this.staticCtx.fillStyle = '#0a192f';
        this.staticCtx.fillRect(0, 0, this.width, this.height);

        this.staticCtx.save();
        graphicNodes.forEach(node => {
            this.staticCtx.fillStyle = node.color;
            this.staticCtx.beginPath();
            this.staticCtx.arc(node.x, node.y, node.radius, 0, Math.PI * 2);
            this.staticCtx.fill();
        });
        this.staticCtx.restore();

        this.isDirty = false;
    }

    /**
     * Executes the main render pass. Transfers pre-rendered pixels using
     * ultra-fast hardware blitting before drawing dynamic interactive overlays.
     */
    render() {
        // Step 1: Blit static background graphics from offscreen buffer in a single call
        this.ctx.drawImage(this.staticCanvasCache, 0, 0, this.width, this.height);

        // Step 2: Render dynamic animated components on top
        const poolLength = this.dynamicNodePool.length;
        for (let i = 0; i < poolLength; i++) {
            const node = this.dynamicNodePool[i];
            if (!node.active) continue;

            this.ctx.fillStyle = node.color;
            this.ctx.fillRect(node.x, node.y, node.width, node.height);
        }

        // Loop animation pass aligned with screen refresh cycle
        this.animationFrameId = requestAnimationFrame(this.render);
    }

    /**
     * Clean up resource bindings to prevent memory leaks during unmounts.
     */
    destroy() {
        if (this.animationFrameId) {
            cancelAnimationFrame(this.animationFrameId);
        }
        this.dynamicNodePool = [];
        this.staticCanvasCache.width = 0;
        this.staticCanvasCache.height = 0;
    }
}
Passing `{ desynchronized: true }` when calling `getContext('2d')` instructs the browser engine to bypass the standard window compositor completely. This reduces frame latency by rendering directly to the screen's front buffer, making it an ideal flag for high-speed interactive drawing tools and lower-latency stylus interaction platforms.
A continuous graphical canvas rendering loop running at 60 FPS provides a window of roughly 16.6 milliseconds to calculate state updates and submit draw commands. If object instantiation inside your render loop triggers frequent JavaScript engine Garbage Collection (GC) pauses, users will experience severe visual micro-stuttering ("jank"). Allocating transient objects, creating new vectors, or constructing short-lived anonymous arrays inside `requestAnimationFrame` loops constantly churns through heap memory allocations.
When the V8 or JavaScriptCore GC engine runs a "stop-the-world" mark-and-sweep phase to reclaim unreferenced heap memory, execution halts entirely. To achieve fluid, stutter-free performance indefinitely, software engineers must adopt low-level memory allocation techniques similar to C/C++ game engines:
While 2D Canvas context optimizations yield significant performance improvements, all execution code still runs single-threaded alongside user event handlers, network operations, and data parsing routines. In complex applications such as CAD software, GIS mapping platforms, or visual photo editors, heavy calculations can still lock up main-thread responsiveness.
The modern solution involves decoupling rendering logic entirely from the DOM main thread through the `OffscreenCanvas` API. By transferring control of an HTMLCanvasElement context to a background Web Worker thread using `canvas.transferControlToOffscreen()`, all calculation loops, batch drawing routines, and geometry processing execute in parallel on a separate CPU core. Even if the main UI thread freezes under intense network or data load, the rendering engine continues running smoothly at full native frame rates.
Are you building complex vector graphics platforms, WebGL engines, or real-time data visualization suites? Reach out to our technical architecture group to explore bespoke high-performance web graphics solutions.
Exploring predictable state synchronization patterns across multi-user web environments.
Read Full Article
How client-side cryptography safeguards graphic design deliverables in modern browsers.
Read Full Article